Anthropic introduces conversation self-assessment as a first layer of abuse detection
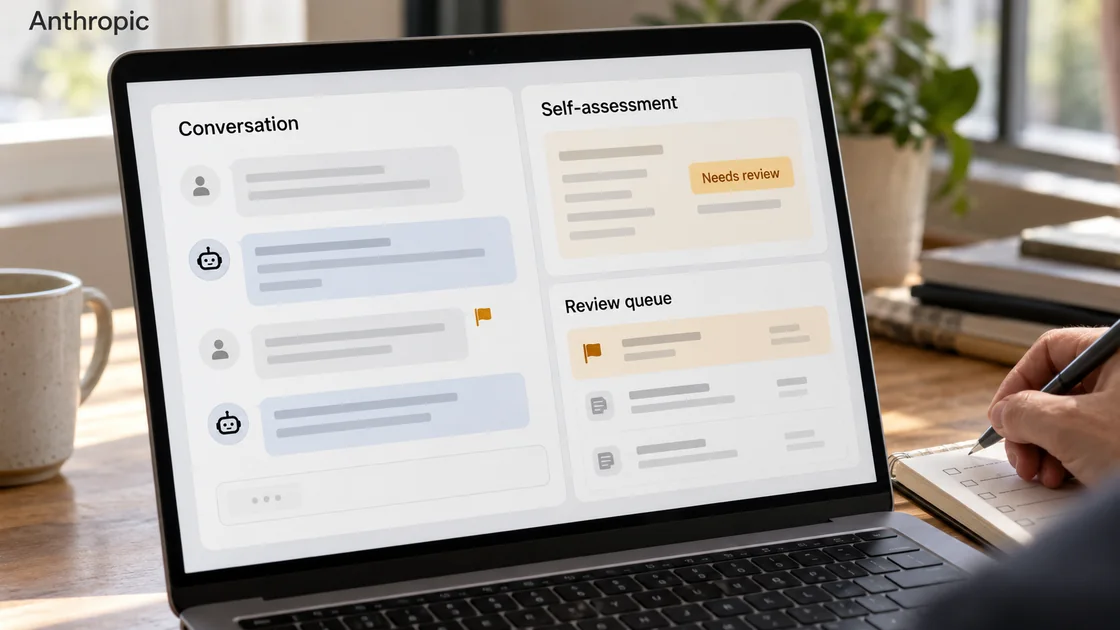
Anthropic published research in which a model makes an initial assessment of conversation safety after responding, then passes the results to subsequent review. The vendor positions this as one part of layered protection, explicitly noting that self-assessment cannot identify all harmful conversations and is insufficient on its own to stop deliberate attacks.
Source Facts
On 16 October, Anthropic introduced a self-assessment method in which Claude makes an initial safety assessment of the entire conversation after responding, including possible risk categories and priorities for human handling. Results feed into broader offline monitoring and subsequent investigation.
The vendor says this approach uses existing conversation context to reduce additional processing costs, alongside other classifiers and real-time protections. It also states limitations: self-assessment can miss harmful activity and should not be the sole defence against deliberate model manipulation.
Businesses can use the triage approach as a reference, letting AI organise items for investigation while retaining independent rules, activity logs and human review, rather than letting one tool decide that everything is normal.
Original sources
Scaling Misuse Detection with Self-Assessment
Sources checked: 2026-10-25 · Compiled with SI agent assistance; not individually reviewed by a human.
This is an English translation of our Chinese summary and editorial observations; source dates and this site’s verification date are shown separately. If an original advisory changes, refer to the source.
KEEP READING
Recommended reading
 Illustration
LiteLLM explains package compromise: exposed keys must be revoked to complete the response
 Illustration
SOCRadar examines SI agent-assisted extortion: human approval remains part of the intrusion process
 Illustration